-
Idempotent pipeline steps are the single highest-leverage design decision you can make early.
-
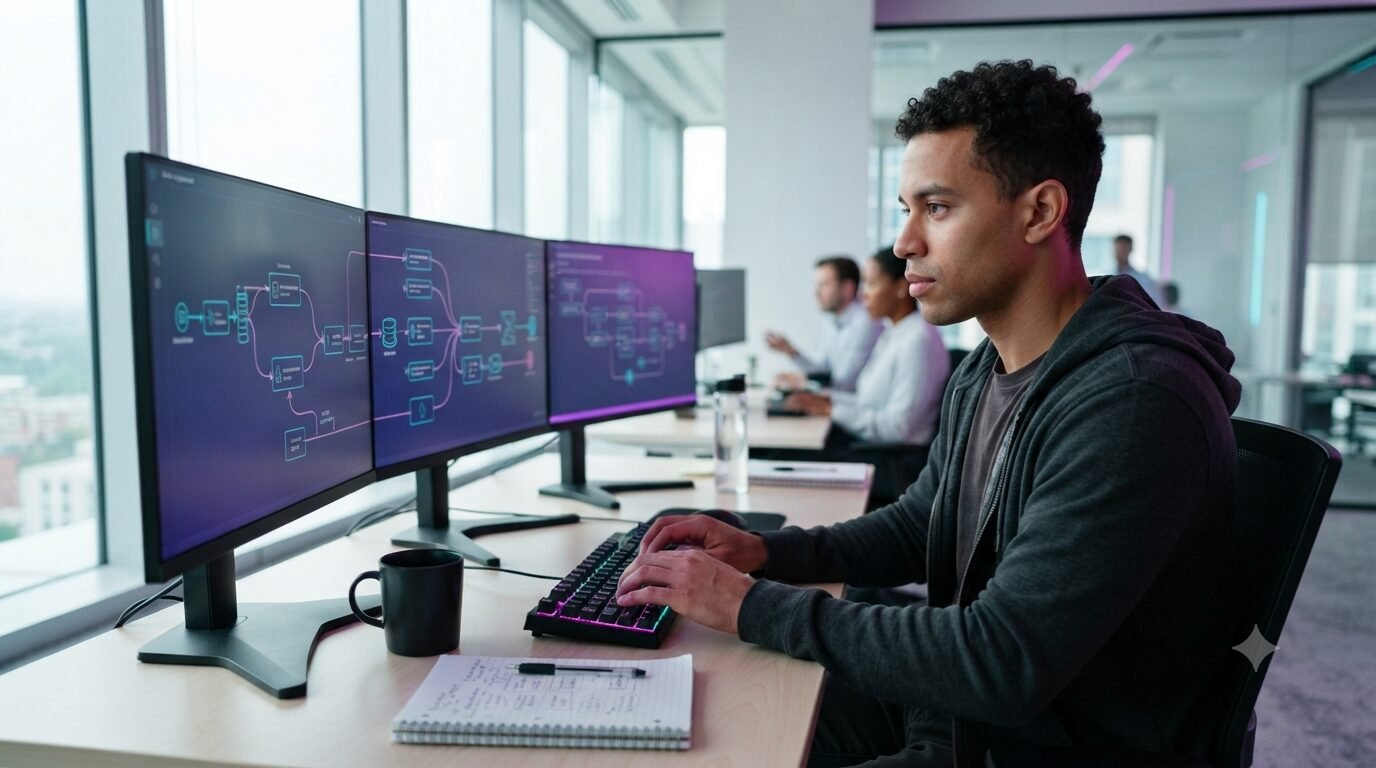
Decoupling ingestion from processing stops a downstream slowdown from cascading.
-
Instrument the pipeline itself, not just the dashboards built on top of it.
-
Load-test against 100x current volume before you actually need the headroom.
The most common data engineering mistake we see is a pipeline that works great in a demo and falls over the first time real production volume hits it. It's rarely a single catastrophic failure — it's a slow accumulation of dropped records, silent duplicate processing, and dashboards that quietly drift from what actually happened.
Make Every Step Idempotent
A pipeline step is idempotent if running it twice on the same input produces the same result as running it once. Without this property, every retry after a failure risks duplicating data — and retries are inevitable at scale. This is the single highest-leverage design decision in any pipeline, and it's far easier to build in from the start than to retrofit later.
Decouple Ingestion From Processing
When ingestion and processing are tightly coupled, a slowdown anywhere downstream backs up the whole pipeline, and a spike in incoming data can overwhelm processing capacity instantly. A queue between the two lets each side scale independently and gives you a natural buffer during traffic spikes instead of a cascading failure.
Instrument the Pipeline, Not Just the Dashboard
Most teams monitor the dashboards downstream of a pipeline and assume that's sufficient. It isn't. If you can't tell why yesterday's numbers look wrong without reading raw application logs, the pipeline itself isn't observable enough — you need metrics on records processed, records dropped, and processing latency at every stage, not just on the final output.
Plan for 100x Before You Need It
You don't need to over-engineer for scale you'll never reach, but you should know where the pipeline's actual breaking point is before you hit it in production. A load test against 100x current volume, run before launch, tells you whether the architecture holds or needs rework — and it's far cheaper to find that out in a test environment than during a real traffic spike.
Schema Changes Are the Quiet Killer
Pipelines rarely break because of volume alone — they break because an upstream schema changed and nothing downstream was built to handle it gracefully. Version your schemas, validate incoming data against an expected shape, and fail loudly (and safely) when something doesn't match, rather than silently processing malformed data.
None of these principles are exotic. They're the difference between a pipeline you build once and one you quietly rebuild every time the product succeeds enough to need it.
Notes from the engineers and strategists at S3Dynamis, drawn from active client engagements across AI, software engineering, and data.