-
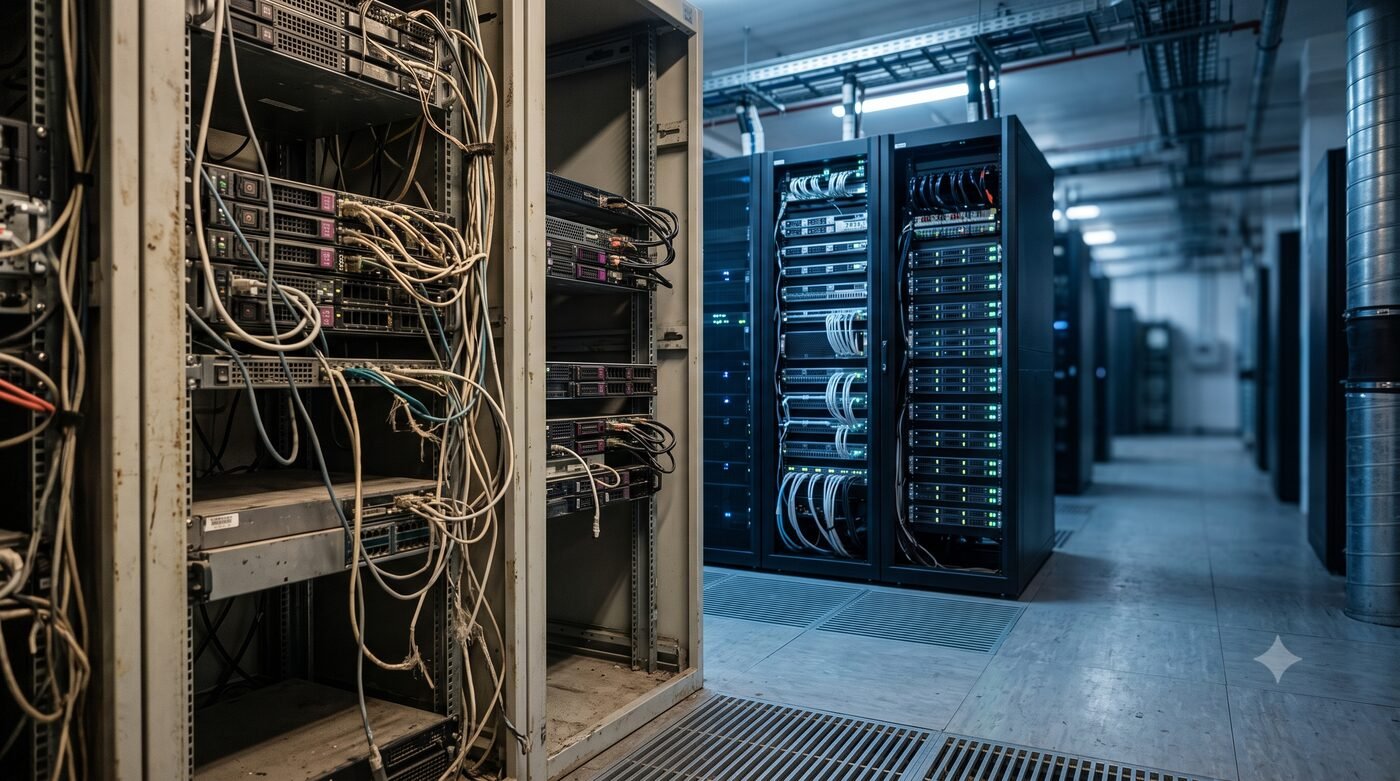
Most AI projects fail on data reliability long before the model becomes the bottleneck.
-
Start from the decision the feature needs to support, not the model architecture.
-
A simple baseline reveals whether the problem is tractable before you invest in complexity.
-
Design for the model being wrong — a review queue beats hoping errors stay rare.
Most AI projects don't fail because the model is bad — they fail because the data pipeline feeding it was never built to be reliable, or because nobody defined what "good enough" looked like before the project started. By the time that becomes clear, months of engineering time are already spent chasing a moving target.
Start With the Decision, Not the Model
Before any model work begins, we ask: what specific decision does this need to support, and who makes it today without AI? If a human is currently making that call from a spreadsheet, the AI's job is to make that same decision faster or more consistently — not to invent a new workflow nobody asked for.
Audit the Data Before You Trust the Roadmap
The single biggest predictor of whether an AI project ships on time is whether the team audited data quality and volume before committing to a timeline. If you don't have enough labeled examples, or if the examples you have don't reflect the cases the model will see in production, no amount of engineering talent will save the schedule.
Build the Smallest Version That Could Work
Resist the urge to reach for the most sophisticated model architecture on the first attempt. A simple baseline — sometimes even a rules-based system — tells you within days whether the problem is tractable with the data you have. Only invest in a bigger model once the baseline proves the approach and reveals exactly where it falls short.
Design for the Wrong Answer
Every production AI system will be wrong sometimes. The question is what happens next. Build a clear path for humans to catch and correct mistakes — a review queue, a confidence threshold that routes uncertain cases to a person, a feedback loop that improves the model over time. Systems that treat "the model was wrong" as an edge case instead of a certainty tend to erode user trust fast.
Ship, Then Iterate
Shipping a narrow, well-scoped AI feature and iterating based on real usage beats a six-month cycle chasing model perfection almost every time. The fastest way to find out what your model actually gets wrong in production is to put it in front of real users behind a feature flag, not to keep testing against a static validation set.
None of this requires cutting-edge research. It requires treating AI like the rest of your software: define the outcome, respect the data, ship small, and build in a way to catch it when it's wrong.
Notes from the engineers and strategists at S3Dynamis, drawn from active client engagements across AI, software engineering, and data.